Checkout Usability Testing Playbook
Master checkout usability testing with this step-by-step playbook. Learn to design scenarios, run tests, and fix friction using Uxia's synthetic testers.

Baymard Institute's long-running research puts average global cart abandonment at around 70.19%, later summarized as 70.22% in its 2026 materials, after aggregating 49 studies over 14 years of tracking (Baymard's checkout research). Roughly 7 in 10 sessions that reach the cart still fail before purchase completion, so checkout usability testing isn't a final polish exercise. It's revenue protection.
The difficult part is that abandonment rarely comes from one visibly broken button. Customers hesitate when an address field rejects valid input, an error appears without explaining how to recover, a mobile keyboard covers the next action, or a payment provider takes them somewhere they don't trust. Those moments often leave no useful explanation in analytics.
This playbook treats checkout usability testing as a full cart-to-payment investigation. It covers realistic tasks, test environments, metrics, evidence capture, prioritization, and a worked example using AI synthetic testers for continuous validation.
Understanding the True Cost of Checkout Friction
Baymard's benchmark of 180+ leading ecommerce sites found that 64% of desktop sites, 63% of mobile sites, and 46% of apps scored “mediocre” or worse in checkout usability. Only 2% of desktop sites received a “good” rating. Mature ecommerce organizations still ship flows that create avoidable uncertainty, so checkout testing must examine the full cart-to-payment journey rather than form length alone.

Why field counts aren't enough
A form-length review can identify unnecessary fields, yet miss whether the browser places the cursor correctly, autofill enters the right values, or validation preserves what the customer already typed. A heuristic review may confirm that an error message exists while missing the fact that a screen reader never announces it.
Analytics show where users leave, but rarely explain why. A discount-code field may distract them, an inline error may appear before they understand the requirement, or a third-party payment handoff may create distrust. Customers often close the tab instead of reporting the problem, leaving the team with a clean-looking funnel and an incorrect diagnosis.
A useful audit traces each transition:
Cart review: Check total-cost clarity, shipping expectations, item changes, and the route into checkout.
Account selection: Verify that guest checkout is visible and that registration wording does not imply an account is mandatory.
Shipping and billing: Observe autofill, field focus, address validation, keyboard behavior, and preservation of entered data.
Payment and review: Test provider handoffs, failure recovery, order summaries, and editing.
Confirmation: Confirm that success status, order details, and receipt information are unmistakable.
Practical rule: Treat every transition as a test surface. A checkout can pass isolated field checks and still fail as a complete journey.
Baymard's checkout usability research covered 25 rounds with 4,400+ participant/site sessions. Each participant tested 5–8 checkouts in about 1 hour, revealing 2,700+ checkout-specific usability issues. Its practical benchmark places the average checkout at 39 usability issues (Baymard's checkout usability research). These findings support testing that captures hesitation, recovery, and trust across the entire journey.
Use Quikly's checkout optimization tips for practical tactics, then map the journey with a user flow diagram. AI synthetic testers can repeat these paths across devices, payment states, and error conditions, giving teams a scalable way to detect friction between scheduled research sessions. The goal is to map every point where customers must interpret, backtrack, re-enter, wait, or recover.
Designing Realistic Checkout Testing Scenarios
A task such as “buy a shirt” produces limited evidence. Participants usually follow the clearest route, ignore optional interactions, and describe impressions only after finishing. A realistic mission gives them a reason to shop, introduces a constraint, and creates opportunities to expose friction across the cart-to-payment journey.
Use real users in moderated 1:1 sessions and ask them to explain their reasoning with the Think Aloud protocol. This captures hesitation, assumptions, and recovery decisions as shoppers move through the flow. Synthetic testers can extend the same scenario across browsers, devices, personas, and payment states, but they should validate human findings rather than replace the context that explains why confusion occurs.

Start with a mission, not a feature
Write the task from the shopper's perspective. Include a product, a constraint, and a reason for completing the purchase. Do not tell participants where to click or reveal the problem under investigation.
You're buying a gift for a colleague. Choose the available size and colour, apply the promotional code provided in the task, use guest checkout if it's available, and have the order delivered to the supplied address. Stop before any real payment is submitted.
The prompt creates observable decisions without dictating the interface. The participant must find the promotion field, determine whether guest checkout is available, enter delivery details, and identify the safe stopping point. It also tests whether the interface communicates progress and risk clearly.
Build a scenario set that exposes failure modes
Give each risk area its own mission. Packing every edge case into one task creates an unnatural journey and makes the evidence harder to interpret.
Discount handling: Provide a valid code, an expired code, or a code with a minimum-order condition. Check whether shoppers find the field and understand the result.
Inventory changes: Begin with an item that becomes unavailable or changes quantity. Observe whether the customer understands the update and restores the rest of the cart.
Address validation: Use an address format that challenges autocomplete or a postcode requiring correction. Record whether valid fields remain intact and focus moves to the problem.
Account walls: Compare guest and returning-user routes. Note whether an account prompt interrupts purchase intent or appears mandatory.
Payment constraints: Test a card failure and a third-party wallet handoff in a safe environment. Check whether the button sets expectations and whether shoppers can return after provider failure.
Accessibility conditions: Run keyboard-only and screen-reader scenarios. Check labels, focus order, announcements, target sizing, and error recovery.
These conditions represent ordinary sources of friction, including promotions, stock updates, device differences, accessibility needs, and payment restrictions. AI synthetic testers can repeat the missions continuously, exposing regressions between scheduled human sessions.
Define the evidence before the session
Success criteria should describe behaviour, not only whether an order reaches completion. Record whether the tester:
Reaches each stage without unexplained backtracking.
Finds and applies the intended promotion.
Understands visible costs and delivery expectations.
Recovers from validation or payment errors.
Retains entered information after an error.
Recognizes when the order is complete.
Operates the flow with the assigned accessibility constraint.
Use the checkout scenario template from Uxia to standardize mission wording and evidence fields. Keep prompts neutral, define a safe stopping point, and avoid telling participants that the checkout contains a known defect. Their confusion, hesitation, and recovery attempts are evidence. Capture those signals in human sessions, then use synthetic testers to check whether the same friction appears across the wider set of journey conditions.
Setting Up the Test Environment and Recruiting Testers
Checkout research fails before the first session when the environment is unsafe or unrealistic. A production flow can trigger real charges, reserve inventory, send fulfilment instructions, or expose personal data. A mockup can avoid those risks but hide behaviours that only appear when payment widgets, address services, browser autofill, and redirects operate together.
Create a staging environment that mirrors production interactions while preventing financial consequences. Use test payment credentials supplied by the payment processor, synthetic addresses, controlled inventory, and an explicit stop before order submission. Confirm that confirmation emails, analytics events, stock changes, and external redirects behave safely.
Human sessions and synthetic coverage serve different needs
Moderated human sessions remain valuable when researchers need rich emotional context, clarification, or observation of a particular audience. They also introduce scheduling, recruitment, consent, device coordination, and facilitator availability. A small panel can reveal important issues, but it may not cover every browser, operating system, persona, payment path, and failure state that the team needs to monitor.
AI synthetic testers are useful for repeatable, broad scenario coverage. In Uxia, teams can define a mission and audience, then deploy synthetic testers aligned to demographic and behavioural profiles across product flows. The platform generates unmoderated interactions, captures think-aloud transcripts, flags usability, navigation, copy, trust, and accessibility issues, and summarizes patterns in reports with metrics, heatmaps, and prioritized insights.
That doesn't make synthetic testers a replacement for every human study. Their strength is scale and repetition. Human research helps explain lived experience and sensitive motivations; synthetic testing helps teams inspect many variants quickly and rerun the same missions after a design or implementation change.
Test the device conditions customers actually use
A desktop browser session can't reliably reproduce mobile behaviour. Use physical devices where possible and test:
Mobile layout: Check whether sticky actions remain visible and whether touch targets are easy to activate.
Keyboard interaction: Observe whether the virtual keyboard obscures fields, buttons, or error messages.
Autofill: Verify that names, addresses, email fields, and payment details populate the intended controls.
Network variation: Watch loading states, delayed validation, duplicate submissions, and recovery after a request fails.
External payment flows: Confirm that redirects, browser back actions, authentication steps, and return states preserve context.
The test environment should let you compare the same mission across these conditions without changing the task itself. That makes the resulting friction map much more useful than a collection of unrelated observations.
Use the following walkthrough to see how an AI-assisted testing workflow can fit into a product review process.
Running the Test and Capturing Friction Points
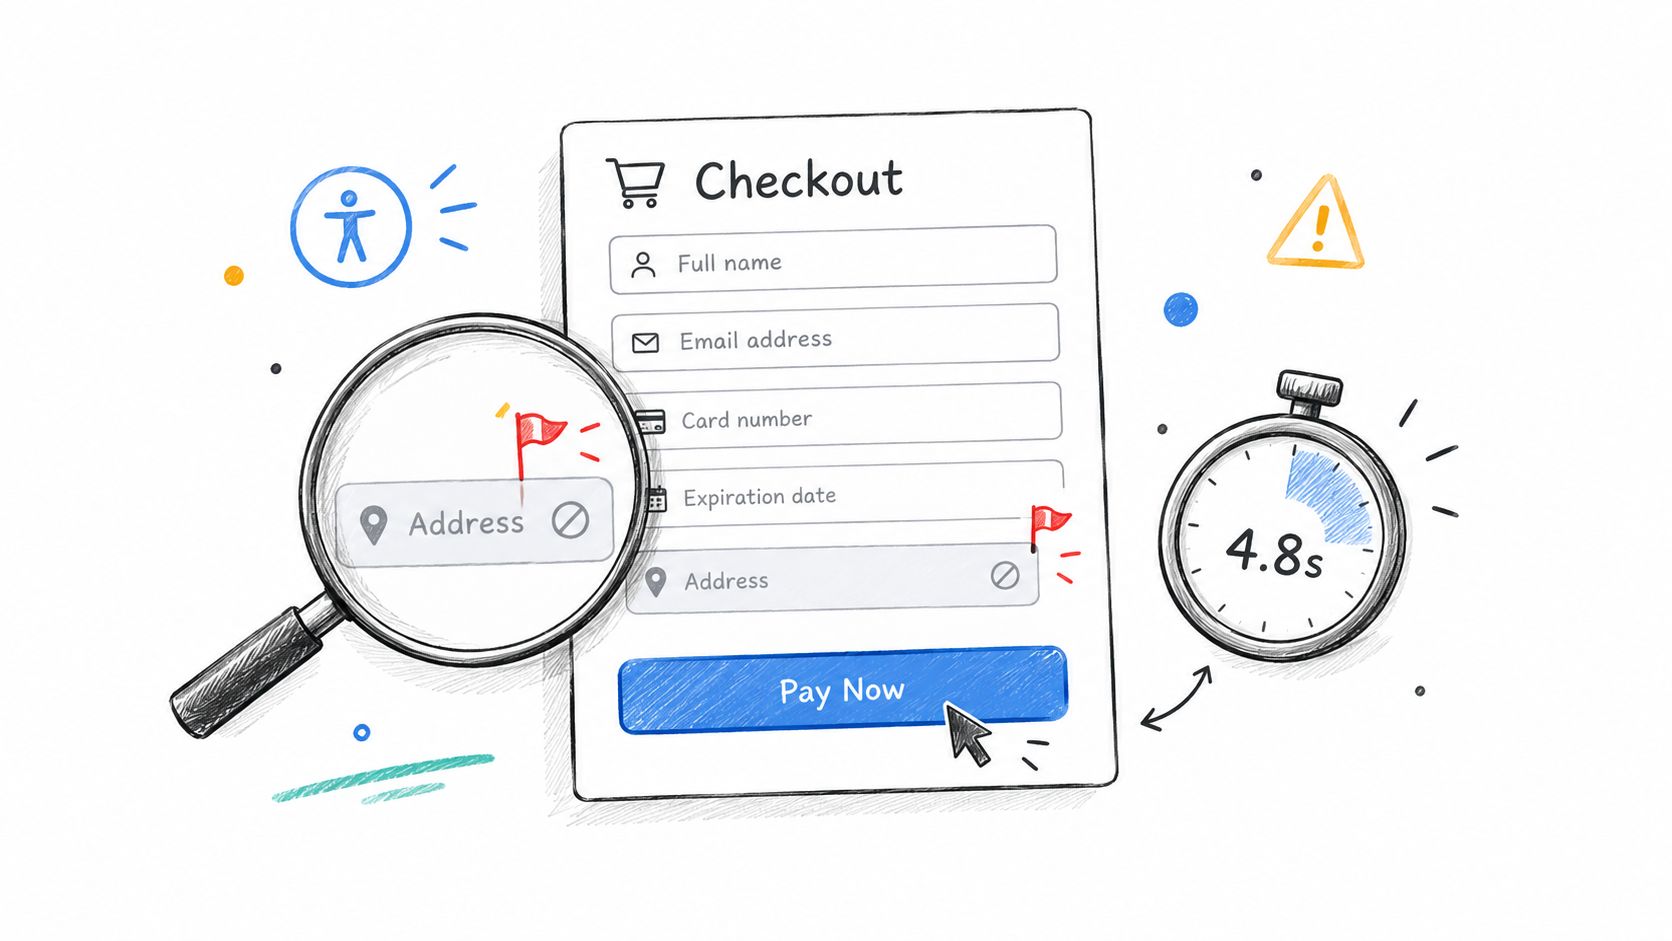
The most revealing moment is often a pause that looks insignificant in a completion report. A tester reaches the payment step, scans the page, opens a different option, returns to the card form, and says nothing. That sequence can indicate uncertainty about security, an unexpected requirement, or a button that doesn't communicate the next action.
Capture behaviour at each stage
Use a structured observation sheet with the checkout stage, device, scenario, observed behaviour, evidence, user impact, severity, recommendation, owner, and status. Write what happened, not only your interpretation.
At the cart, record whether the customer can understand the total and delivery conditions. At account selection, note whether guest checkout is visible and whether login language creates a forced-account impression. During shipping, watch focus movement, autocomplete, field labels, validation timing, and whether an error clears previously entered values.
Payment deserves separate scrutiny. A third-party provider may introduce a new visual language, unfamiliar authentication step, or unclear return path. Test whether the primary action accurately describes what will happen, whether a failed payment preserves usable information, and whether the customer can tell if the order was submitted once or multiple times.
Test accessibility as a purchase condition
Accessibility isn't a separate compliance exercise that can be postponed until the end. Checkout is a sequence of dependent interactions, so one inaccessible control can block the entire purchase.
Look specifically for:
Unlabeled controls: A screen reader user should understand the purpose of every field and button.
Silent errors: Error messages need to be announced and associated with the relevant input.
Keyboard traps: Users must be able to move into, through, and out of dialogs, widgets, and payment components.
Unclear focus: The active control should remain visually apparent as the interface changes.
Small targets: Mobile controls need enough space for reliable touch interaction.
Redundant entry: The flow shouldn't force customers to repeat information that the system already has.
Current accessibility guidance also highlights WCAG 2.2 concerns involving redundant entry, authentication, and target sizing. Test these conditions with the actual components in the checkout, including embedded payment fields and authentication handoffs, rather than relying only on a static accessibility scan.
Record trust and recovery signals
Customers assess risk while entering personal and payment information. Capture whether the site explains delivery, returns, fees, secure payment, and the next step at the moment those questions arise. A security badge alone won't repair a confusing redirect or a total that changes late in the journey.
A strong session record links the visible trigger to the resulting behaviour: the customer sees an unexpected fee, pauses, searches for clarification, edits the address, receives an unclear error, or abandons the flow. That chain is more actionable than a label such as “checkout feels confusing.”
Analysing Results and Prioritising Fixes
A transcript becomes useful only after the team converts it into a decision. Start by grouping observations by stage, then separate symptoms from causes. “User stopped at payment” is a symptom. “The payment button didn't explain that it opened an external provider, and returning lost the cart context” describes a fixable interaction problem.
Build a friction map
Create one row for every distinct issue, even when several testers encounter it. Preserve the evidence link, device condition, mission, and affected audience. Then assign three judgments:
Harm: How much does the issue block progress, create rework, reduce trust, or risk an incorrect order?
Reach: Which missions, devices, payment methods, or user groups encounter it?
Confidence: How directly does the evidence support the suspected cause?
This model prevents the loudest comment from automatically becoming the top priority. A minor copy complaint may be widespread but low harm. A keyboard trap may appear in fewer sessions yet completely block a group of customers.
Worked example
Suppose a test produces three findings:
On mobile, the address error appears below the visible viewport and doesn't move focus. Testers continue editing other fields before discovering it.
The guest option is present but visually subordinate to account creation. Several participants look for a way to continue without registering.
A payment failure returns the customer to the form, but the card details have been cleared and the error doesn't explain the correction required.
The first issue has high harm because it blocks recovery, broad reach across mobile address tasks, and strong confidence if recordings show repeated missed errors. The second creates hesitation and unnecessary effort, while the third combines payment risk with re-entry cost. All three deserve more attention than a cosmetic spacing issue, even if the spacing comment sounds more frequent.
For Uxia, a complete purchase mission can generate the transcript and issue flags needed for a stage-by-stage friction map. Human researchers should still review representative evidence, challenge assumptions, and validate high-impact changes with real customers when the decision affects a sensitive audience.
Checkout Friction Prioritization Matrix
Issue Category | Harm Level | Reach | Action Required |
|---|---|---|---|
Payment failure clears entered details | High | Broad across payment-failure missions | Preserve recoverable data, clarify the error, and retest the full recovery path |
Mobile address error remains out of view | High | Mobile address scenarios | Move focus or provide an accessible error summary, then test keyboard and screen-reader behaviour |
Guest checkout is visually subordinate | Medium to high | New-customer scenarios | Make the route explicit and compare account and guest paths |
Optional field lacks clear labeling | Medium | Most standard purchases | Clarify the label and monitor hesitation in follow-up testing |
Decorative spacing inconsistency | Low | Broad but non-blocking | Schedule with routine UI maintenance |
Use harm, reach, and confidence to explain the order of work to stakeholders. The resulting report should connect each recommendation to evidence, an owner, and a retest condition. Avoid claiming that a fix will produce a specific conversion lift unless a controlled experiment demonstrates it.
Continuous Validation with Synthetic Testers
Checkout changes constantly. A new wallet, promotional module, address provider, authentication rule, or responsive component can introduce friction into a path that passed last month's review. A quarterly research sprint may discover the regression after customers have already encountered it.
Continuous validation creates a different operating rhythm. Store checkout missions alongside design review and release criteria, then rerun the relevant journeys when the cart, shipping, payment, account, or confirmation experience changes. Compare transcripts and issue flags against the previous baseline, focusing on newly introduced hesitation, new error states, and changes in recovery.
Use automation where repetition matters
Synthetic testers are well suited to repeatable checks such as:
Guest purchase on mobile and desktop.
Returning-user purchase with saved details.
Discount-code success and failure.
Address validation and correction.
Third-party payment redirection and return.
Keyboard navigation and accessibility constraints.
Confirmation clarity after a successful test order.
The synthetic users guide for website validation describes the broader pattern. Teams can use the same approach for checkout by defining stable missions, isolating the environment, and reviewing changes rather than treating every run as a new study.
Keep human judgment in the loop
Automation shouldn't turn usability into a pass-or-fail gate. A transcript may reveal hesitation but not fully explain a cultural expectation, a sensitive trust concern, or a research question that needs direct conversation. Use synthetic validation to widen coverage and shorten feedback loops, then reserve moderated human studies for ambiguous, high-risk, or strategically important findings.
The operational metric is not “number of tests run.” It's whether the team catches meaningful friction before release, assigns a clear fix, verifies the fix under the affected conditions, and keeps accessibility and trust requirements visible throughout delivery.
Uxia lets product teams define checkout missions, deploy synthetic testers across audience and device profiles, and turn interactions into transcripts, issue flags, heatmaps, and prioritized reports. Use Uxia to validate your cart-to-payment journey before the next release, then rerun the same scenarios whenever the flow changes.